Picture a camera above a supermarket checkout lane, producing about 30 pictures every second. Software has to find every person and trolley in each picture, draw a box around each, and pass the result along before the next picture arrives. If it takes too long, frames pile up and the numbers stop meaning anything.
That job is called real-time object detection, and for the past few years a large share of the teams doing it have reached for the same tool first: YOLOv8, released by the company Ultralytics in January 2023.
In 2026, YOLOv8 is no longer the newest model in its family. Ultralytics shipped YOLO11 in 2024 and YOLO26 in January 2026, and both beat it in benchmark tests. Even so, YOLOv8 still runs inside plenty of shipped products, and most online courses were written for it. This guide explains how it works, where it goes wrong in real deployments, and how to decide whether it belongs in your product.
What YOLOv8 actually does
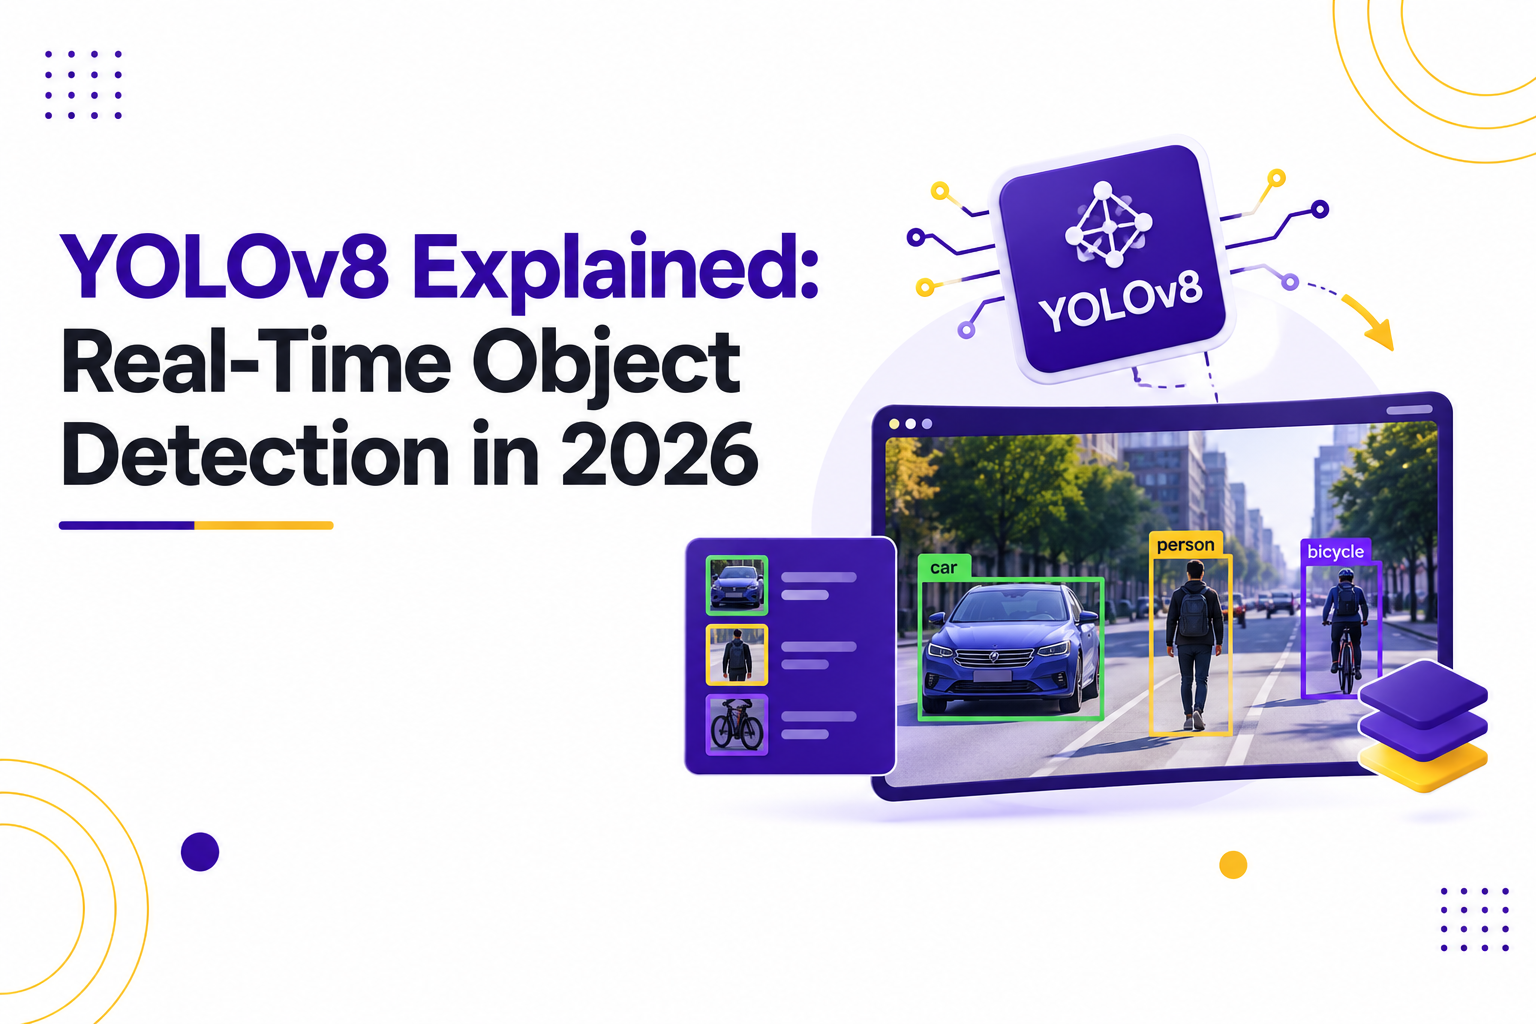
Hand YOLOv8 a photo and it hands back a list. Each entry answers three questions: what is this, where is it, and how sure are you? The "where" is a rectangle described by four numbers. The "what" is a label such as person, forklift or cardboard box. The "how sure" is a confidence score between 0 and 1. One line of output might read: person, 0.91, at these coordinates.
That is what YOLOv8 object detection means in practice. The model has no idea that the person looks impatient. It spots things it was trained to spot and reports where they are. Anything smart a product does afterwards, like counting or sending an alert, is ordinary code written on top of that list.
The name comes from a 2015 research paper by Joseph Redmon and colleagues called "You Only Look Once." Detectors of that era first proposed thousands of regions that might contain an object, then classified each region separately. YOLO folded both steps into a single pass through one neural network, which is why the family became known for speed.
A computer vision model is a program that has learned to recognize patterns in pixels by studying a large collection of labeled images. YOLOv8 ships already trained on COCO, a public dataset with 80 everyday categories such as people, cars, bicycles, dogs, cups, chairs and laptops. You can use it as it comes, or retrain it to recognize things specific to your business, like a crack in a weld.
The version numbers trip people up. Ultralytics built YOLOv8, YOLO11 and YOLO26, while YOLOv9 and YOLOv10 came from separate academic groups. A higher number does not automatically mean a better fit for your use.
How the model looks at an image
You don't need the internals to use YOLOv8, but a rough mental picture helps when results look wrong. The network has three sections.
The backbone comes first. It pulls out visual features at several scales, from edges and textures to shapes and object parts. This stage notices "something round and shiny is here" without deciding what it is.
The neck mixes those scales together. Small objects show up best in the fine, detailed layers, while large objects make more sense in the coarse ones. The neck passes information between them so a distant pedestrian and a nearby bus can both be found.
The head makes the final call. For each cell of a grid laid over the image, it predicts whether an object is centered there, its class, and how far its box stretches to each edge.
Three design choices separate YOLOv8 from the YOLO versions before it. The first is that it is anchor-free. Older versions started from a fixed menu of box shapes, called anchors, and nudged them to fit each object. Objects with odd proportions, like long pipes, fit those presets badly. YOLOv8 predicts the center point and distance to each edge directly, so no anchor tuning is needed.
The second is a split head. One branch answers "what is it?" and another answers "where exactly is it?" The two questions need different kinds of features, so keeping them apart helps both. The third is a backbone block called C2f, which sends information along parallel paths before merging it. You won't configure it, but it's part of why a small YOLOv8 network stays accurate.
One more step happens after the network finishes, and it matters later in this article. The model makes many overlapping guesses for the same object. A cleanup rule called non-maximum suppression, or NMS, keeps the most confident box and deletes other boxes that overlap it by more than a set amount. Overlap is measured with IoU (intersection over union), the area two boxes share divided by the total area they cover. NMS is a hand-written rule outside the neural network. It slows down in crowded scenes and can delete real objects standing close together. The newest Ultralytics model, YOLO26, was designed to get rid of it.
Five sizes and five jobs
YOLOv8 comes in five sizes: nano (n), small (s), medium (m), large (l) and extra-large (x). Bigger models are more accurate and slower. The official benchmark figures show how steep that trade-off is.
Source: Ultralytics YOLOv8 documentation. Images at 640 pixels. CPU times use ONNX Runtime; GPU times use TensorRT. Measured on an Amazon EC2 P4d instance.
Two terms in that table need a quick explanation. Parameters are the adjustable numbers inside the network set during training; more of them means more memory and computing. mAP, short for mean average precision, is a score out of 100 that measures how closely the predicted boxes match the real ones across a range of strictness levels. A jump from 37 to 54 sounds modest, but in practice it separates a model that misses many small or partly hidden objects from one that catches most of them.
Watch the CPU column if you're planning a budget. The nano model handles roughly 12 frames a second on a server processor; the extra-large model manages about two. On a data-center GPU, every size finishes in under four milliseconds. So whether YOLOv8 object detection counts as "fast" depends almost entirely on which size you pick and what hardware runs it. A laptop and a cloud GPU will give very different numbers from the same model file.
Detection is only one of the jobs the package handles. The same library offers:
• Detection, which draws a labeled box around each object.
• Instance segmentation, which traces each object's exact outline pixel by pixel.
• Classification, which gives one label to the whole image, for example "defective" or "fine."
• Pose estimation, which finds 17 body points on each person, such as shoulders, elbows and knees.
• Oriented bounding boxes (OBB), which are rotated boxes for objects seen at an angle, like ships in satellite photos or papers lying on a desk.
A built-in tracking mode, using trackers called ByteTrack and BoT-SORT, gives each object an ID that stays with it from frame to frame. Tracking turns "there are four people in this frame" into "this particular person has been in the queue for three minutes."
Why money keeps moving into vision
Research firms agree computer vision spending is growing fast. They disagree widely about its current size.
That is a gap of more than $12 billion for the same year. The difference comes from definitions: some firms count cameras, sensors and chips heavily, while others weight software more. Grand View Research found that hardware made up 71.5% of revenue in 2025, with software as the fastest-growing piece. Mordor Intelligence expects automotive uses to grow fastest, at 18.23% a year through 2031, as cars carry more cameras.
For a business reader, a computer vision model like YOLOv8 sits in the software slice, which is smaller than hardware but growing faster. The shift toward running models on cameras and small devices is exactly the work YOLO models were built for.
YOLOv8 next to the newer models
By 2026, YOLOv8 has been overtaken twice by its own maker.
YOLO11, released in September 2024, swapped some building blocks for more efficient ones and added an attention module, which helps the network focus on the most informative parts of the image.
YOLO26, launched on January 14, 2026, made deeper changes. It removed NMS, so the network outputs final boxes directly. It also dropped a component called Distribution Focal Loss (DFL), which YOLOv8 uses to sharpen box edges but which makes exporting the model to phones and small chips harder. It also added training techniques aimed at small objects. In the company's own tests, the YOLO26 nano model scores 40.9 on COCO and takes 38.9 milliseconds per image on a CPU, against 37.3 and 80.4 milliseconds for YOLOv8 nano.
Outside Ultralytics, YOLOv10 from Tsinghua University (May 2024) was the first numbered YOLO to skip NMS. Ultralytics says a YOLO27 is in final development, with no launch date or public model files yet.
Accuracy and speed figures from Ultralytics documentation, 640-pixel images, CPU times with ONNX Runtime.
So why would anyone still choose YOLOv8? A working system is worth more than a benchmark gain. If your YOLOv8 pipeline already meets its targets, migrating costs engineering time for a gain users may never notice. The volume of written help also matters: most forum answers and courses from 2023 through 2025 assume YOLOv8. And some hardware toolchains were tested against YOLOv8's exact output format, which changes in YOLO26 because NMS is gone.
All three share one Python interface, so swapping "yolov8n.pt" for "yolo26n.pt" starts a migration, though it rarely finishes one.
For real-time object detection in a new project that has to run on ordinary processors, YOLO26 is the sensible default in 2026. For existing systems and for learning, YOLOv8 still earns its place.
The problems the demo never shows
A demo video of YOLOv8 boxing cars on a busy street takes an afternoon. A system that works on your street, at night, in the rain, for a year, takes much longer.
Data gaps: the model only knows what it has seen
The pretrained model knows 80 COCO categories. It has never seen your product, your factory floor or your camera angle. Even for classes it knows, like "person," it learned mostly from photos taken at eye level in decent light. A ceiling camera looking straight down turns people into dark circles with shoulders, and accuracy drops.
Training on your own images fixes this, but your dataset covers only the conditions someone remembered to photograph. Ultralytics' own training advice suggests at least 1,500 images and 10,000 labeled objects per class, plus a small share of background images (up to about 10%) that contain no objects at all, so the model learns what "nothing here" looks like. Most first projects start with far fewer, and most failures in YOLOv8 object detection projects trace back to that shortfall.
The gaps that hurt most are the ones nobody noticed during planning:
• Night shifts, when every training photo was taken in the afternoon.
• Seasonal change, such as winter coats that hide body shapes or snow covering floor and road markings.
• New packaging, when a supplier redesigns a box and the model stops recognizing it.
• Rare events that matter a lot, like a spill or a fallen worker, which appear in only a handful of frames.
The fix is a habit: log low-confidence detections in production, review a sample weekly, label the confusing ones and retrain. A model that is never retrained drifts quietly out of date.
Conflicting signals: when outputs contradict each other
YOLOv8 can be confidently wrong, and it can disagree with itself.
Take a camera in a clothing store. In one frame the model labels an object "person" at 0.62 confidence and, on an overlapping box, "mannequin" at 0.58. (Imagine a custom model trained on both classes.) By default, YOLOv8 runs NMS separately for each class, so both boxes survive, and your counting code now sees two objects where there is one. Turning on class-agnostic NMS (the agnostic_nms=True setting) makes the cleanup compare boxes across classes and keep only the stronger one. That solves this case and creates a new one: two real objects of different types standing close together can now wipe each other out.
Flicker is the other common conflict: a pallet is detected in frame 101, missed in 102 and found in 103, so a "disappeared" alert fires constantly. Trackers help by keeping an object alive for a few frames after it vanishes, and most production systems add a voting rule, such as "the object must appear in 5 of the last 8 frames before we act." That costs a fraction of a second and removes many false alarms.
The confidence threshold defaults to 0.25. Raise it and you get fewer false alarms but more misses; lower it and the opposite happens. No single value is right. A safety system watching for people near moving machinery should accept extra false alarms, while a shopper-counting dashboard can live with a few misses. Set it by what each mistake costs, and if costs differ between classes, filter each class with its own cut-off after prediction.
Real-time decisions: working inside the frame budget
A camera running at 30 frames per second gives you about 33 milliseconds per frame, and the model is only one part of what must fit inside that window.
Illustrative figures for a small model on an edge GPU at 30 frames per second. Real numbers vary widely by hardware, so measure your own pipeline.
Add up the high end of each row and you've blown the budget. You can run detection on every second or third frame and let the tracker fill the gaps, shrink the input from 640 pixels to 480 or 320 (which hurts small objects), or move to a smaller model. Never let frames queue up. A detector slower than its camera falls further behind every second and soon reports events that are long over. For real-time object detection, dropping a stale frame is nearly always better than processing it late.
Look again at the NMS row. Its cost grows with the number of candidate boxes, so your worst delays arrive exactly when a packed entrance gives you the most people to watch. That unpredictability is one reason Ultralytics removed the step in YOLO26.
Exceptions and edge cases
Small objects are the most common complaint. Shrink a 4K frame to 640 pixels and a distant person may end up a few pixels tall. You can train and run at a larger input size such as 1280 pixels, or cut the image into overlapping tiles and run detection on each tile (the open-source SAHI library is often used for this). Both cost extra computing time.
Crowds cause a different problem. When people stand shoulder to shoulder, their boxes overlap heavily, and NMS may merge two people into one. Lowering the IoU threshold makes the merging worse, while raising it lets more duplicate boxes through. Dense crowd counting often needs a different method, such as density estimation, which predicts a head count for an area without boxing each person.
Pictures of things fool the model regularly. A person on a billboard or a car reflected in a shop window looks real at the pixel level. Add such images to training as background, or mark zones in the frame where detections are ignored.
Motion blur smears fast-moving objects indoors, and raising the camera's shutter speed often helps more than any model change.
Label disagreement is the sneakiest edge case. Is a box with one torn corner "damaged"? If two labelers would answer differently, the model learns the inconsistency. Write a one-page labeling guide with example images before anyone starts.
Under pressure: what changes at scale
Two hundred cameras across forty stores is a different project from one camera on a laptop. The first thing to strain is usually hardware throughput, not accuracy. A single GPU can serve many camera streams if you batch frames, meaning you feed several images through the model at once. Batching raises throughput but adds a small wait while each batch fills, so keep batches small for safety alerts.
Exporting to an optimized format helps a lot. The package can convert YOLOv8 to ONNX, TensorRT (for NVIDIA GPUs), OpenVINO (for Intel chips), CoreML (for Apple devices) and TFLite (for Android phones and small boards). TensorRT can also run the model with smaller number formats (FP16 or INT8) for extra speed. INT8 needs a calibration step and can cost some accuracy, so test it on your own footage.
Bandwidth is the quiet cost. Many large deployments run a small model on or near each camera and send only the results, a few hundred bytes of boxes and labels, instead of megabytes of video. Raw footage then never leaves the building, which also helps with privacy rules.
At this scale, a computer vision model needs the same care as any other production software. Each trained version needs a number, a record of its dataset, a way to roll back, and monitoring of confidence scores. A slow drop in average confidence is often the first sign that a camera has been bumped, a lens is dirty or the scene itself has changed.
Plan for failure too. Cameras go offline and networks drop. Decide ahead of time what the system does when it's blind. Silent failure is the worst outcome, because the dashboard keeps showing zero incidents while nothing is being watched.
A short YOLOv8 tutorial: from install to your first custom model
This YOLOv8 tutorial assumes you have Python and a terminal. A GPU is optional, though CPU training is slow.
Step 1: Install the package.
pip install ultralytics
Step 2: Run the pretrained model on an image.
from ultralytics import YOLO
model = YOLO("yolov8n.pt")
results = model("street.jpg", conf=0.25)
for box in results[0].boxes:
print(model.names[int(box.cls)], float(box.conf))
The model file downloads on first use, and you'll see lines such as "person 0.89."
Step 3: Prepare your own data.
Each image needs a matching text file with one line per object: the class number, then the box's center position, width and height, all written as fractions of the image size. Labeling tools such as CVAT and Roboflow export this format. A small settings file tells the trainer where the images are and what the classes are called:
path: datasets/parcels
train: images/train
val: images/val
names:
0: parcel
1: damaged_parcel
Step 4: Train.
model = YOLO("yolov8n.pt")
model.train(data="parcels.yaml", epochs=100, imgsz=640)
Starting from pretrained weights, called transfer learning, means the model already recognizes edges and shapes and only has to learn your categories. By default, training uses mosaic augmentation, which stitches four images into one for extra variety, and turns it off for the final 10 epochs (full passes through the data) so the model finishes on normal-looking images.
Step 5: Check the results.
Training saves charts and scores in a folder called runs. Look past the single mAP number and open the confusion matrix, which shows which classes get mistaken for which. If "damaged_parcel" keeps getting labeled "parcel," you need more damaged examples, and clearer ones.
Step 6: Export for deployment.
model.export(format="onnx")
Replace "onnx" with "engine" for TensorRT, or with "openvino", "coreml" or "tflite", to match your hardware.
Those six steps cover the core of any YOLOv8 tutorial. To try the newer model later, change "yolov8n.pt" to "yolo26n.pt", rerun the same steps, and compare both models on your folder of hard images.
A licensing detail founders often miss
The Ultralytics code and model files are released under the AGPL-3.0 license. Put simply, if you build software with it and offer that software to other people, including as a web service, you may have to publish your own source code under the same license. Many companies building closed commercial products buy an Ultralytics Enterprise License instead. Check this before you ship, and talk to a lawyer if your situation is unclear.
Is YOLOv8 right for your team?
The answer depends on where you sit.
Founders scoping a feature should know the model is the cheap part. Most of the budget goes into collecting and labeling real images, choosing hardware, and the retraining loop after launch. A proof of concept can take days; a dependable product usually takes months.
Developers will find YOLOv8 a gentle way into object detection. For a new production build, prototype with both YOLOv8 and YOLO26, since the code is nearly identical.
Operations and office teams should start from the question. "How many people used meeting room B today?" suits a detector. "Was the meeting useful?" does not. Tasks that come down to spotting, counting or locating visible things are a good match for YOLOv8 object detection. Tasks that need judgment, context or a sense of intent are not.
Content writers should be careful with version claims: "YOLOv8 is the latest YOLO" stopped being true in 2024. A claim that one model is "faster" means little without the size and hardware attached.
Where this leaves you
YOLOv8 turned a hard research problem into something one developer can set up in an afternoon, which is why it spread so widely. In 2026 it is no longer the best performer in its family. YOLO26 beats it on ordinary processors, removes the NMS step that slows down crowded scenes, and keeps the same Python interface, which makes it the natural starting point for new edge projects.
Still, the model choice matters less than most buyers expect. Projects succeed when teams collect data from real conditions, set thresholds based on what mistakes actually cost, plan their frame budget, and keep retraining as the world in front of the camera changes. A team that does those things will get good results from YOLOv8 or YOLO26. A team that skips them will struggle with either.