Why This Matters Right Now
If your marketing team is still waiting days for a simple product photo edit, or your agency pays a photographer for every single social post, you already know why so many businesses have started looking at AI image tools. Stable Diffusion is one of the names that keeps coming up, but a lot of business owners still aren't sure what makes it different from Midjourney, DALL-E, or Adobe Firefly, or whether the setup effort is worth it.
This guide breaks down what Stable Diffusion in 2027 actually looks like for a business. We'll cover what it is, how it's different from the subscription-based tools most people have already tried, and where each one genuinely fits, without the sales pitch.
What Is Stable Diffusion
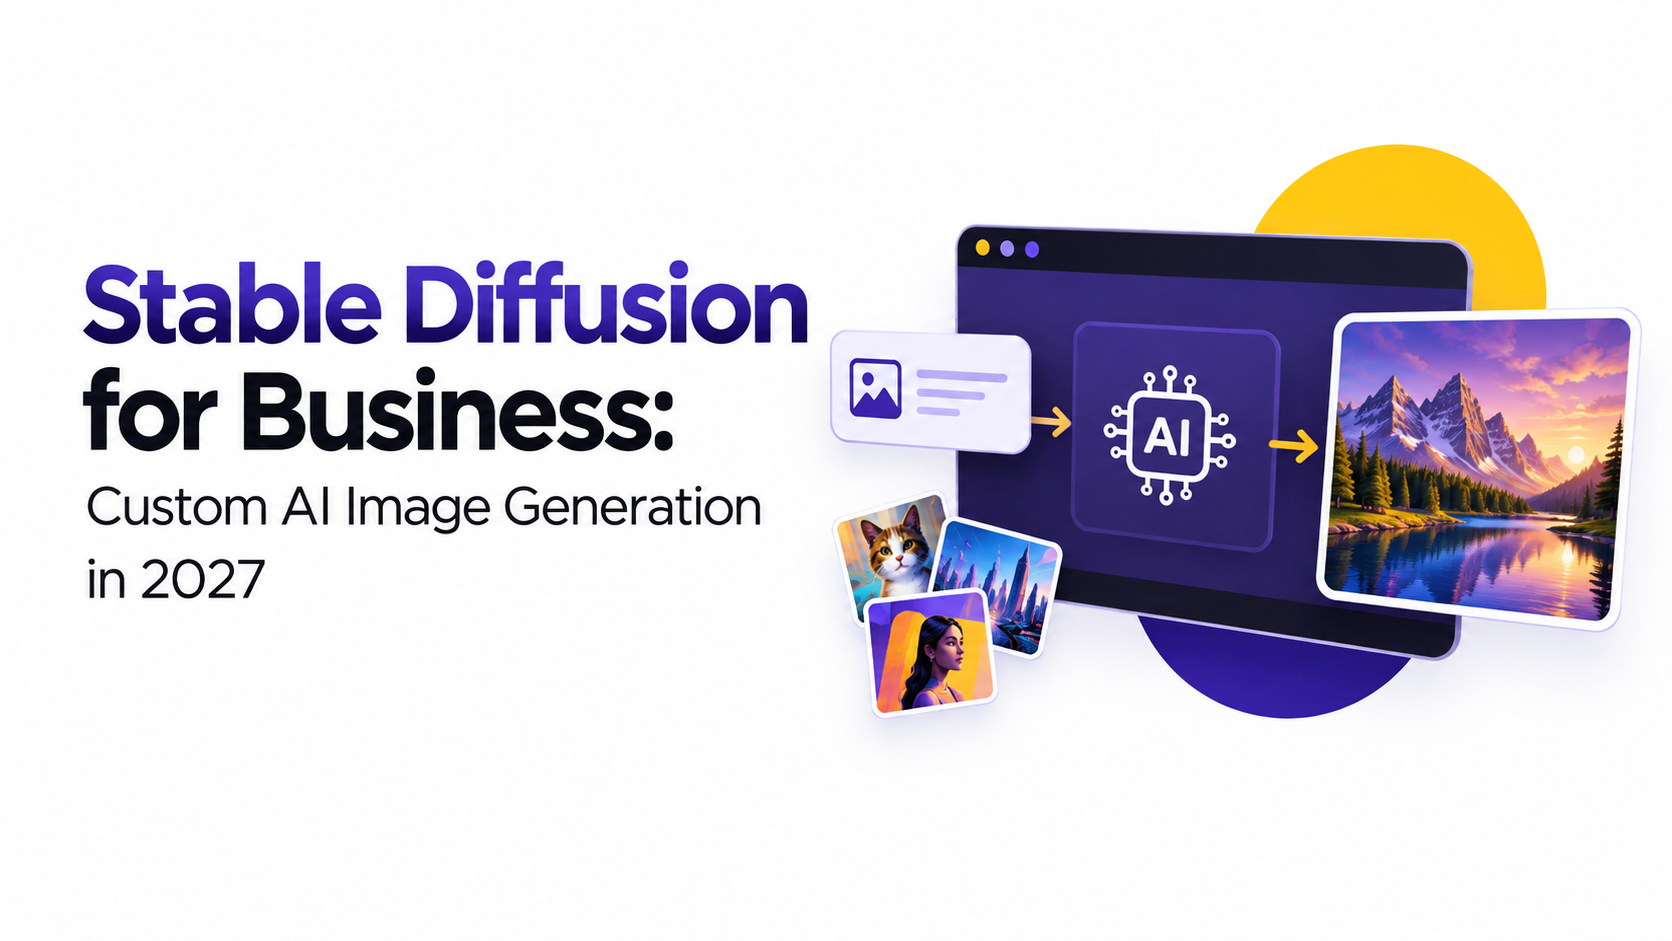
Stable Diffusion is an open-source AI model that turns a text description into a picture. You type something like "a pair of leather boots on a wooden table, soft morning light," and the model builds an image step by step, starting from random noise and gradually shaping it until it matches your description. That step-by-step refining is called diffusion, which is where the name comes from.
Stability AI first released it in 2022. Unlike most AI image tools, the model itself is free to download and run on your own computer or your own cloud server. Nobody hands you a login and a monthly bill, you can just take the files and use them. The model family has grown a lot since then, and the newer versions handle text inside images, multiple subjects in one frame, and specific art styles far better than the early releases did.
Features that matter for a business
• Open weights, no gatekeeping: anyone can download the model and run it, no waitlist and no monthly quota to hit
• Fine-tuning: you can train it further on your own product photos so it learns your exact packaging, colours or poses
• Runs locally or in your own cloud: useful if you don't want customer or product images sitting on someone else's server
• Style control add-ons: tools like ControlNet let you lock the pose or layout of an image while changing everything else
• Lower cost per image at scale: once it's set up, generating thousands of images costs a fraction of a stock licence or a photoshoot
Who actually benefits from this
• E-commerce brands that need hundreds of product photos in different colours, backgrounds and angles
• Game studios producing concept art and texture variations during early prototyping
• Advertising and marketing agencies running localised creative across several markets at once
• Architecture and interior design firms sketching visual concepts before committing to a full 3D render
• Print-on-demand and merchandise businesses that need constant design variety without hiring a designer for every single one
What Are Closed AI Image Platforms
On the other side, you have the subscription tools: Midjourney, OpenAI's DALL-E (built into ChatGPT), and Adobe Firefly. These work differently. You don't get the model itself, you get access to it through an app or website, and the company behind it controls how it runs, what it costs, and what changes from one month to the next.
Features that matter for a business
• No setup: sign up and start generating within minutes, no server, no GPU, no technical staff required
• Polished default output: these tools are tuned to produce good-looking images even from a short, simple prompt
• Built-in legal cover: Adobe Firefly, in particular, is trained only on licensed and public domain images, which matters if copyright disputes worry you
• Updates handled for you: the provider pushes model improvements automatically, so you're never managing versions yourself
• Team plans and brand kits: most now include shared workspaces, saved styles, and usage tracking built for teams
Who actually benefits from this
• Small businesses and solo marketers who need decent visuals fast, without technical staff
• Content creators producing social graphics, blog headers, and quick campaign visuals
• Teams that need strong legal certainty around image rights, such as publishers or large retailers
• Anyone testing AI image generation for the first time without any upfront investment
The Real Difference
The gap between these two approaches isn't really about image quality anymore. Both sides can produce excellent images. The real difference is control versus convenience.
With Stable Diffusion, you own the pipeline. You can retrain it on your own catalogue, run it inside your own app without sending data anywhere, and change how it behaves right down to the code. That flexibility comes at a cost: someone on your team needs to understand how to set it up, keep it running, and fix it when something breaks.
With a closed tool, you're renting access to someone else's system. You don't need any of that technical know-how, but you also can't change how the model behaves beyond what the settings panel allows, and your bill climbs as your usage grows. If the provider changes its pricing, drops a feature, or has an outage, that's outside your control.
There's also a data question worth thinking through. If your business deals with anything sensitive, unreleased products, client mockups under NDA, or regulated imagery, running the model on your own hardware means nothing leaves the building. A cloud subscription, even a well-run one, still means your prompts and outputs pass through someone else's servers.
Comparison at a Glance
Stable Diffusion Development Trends 2027
Here's where the Stable Diffusion development trends 2027 are actually pointing, based on what's already shipped rather than speculation:
• Smaller, faster models: distilled and "turbo" versions now run on a laptop or even a phone, instead of needing a data-centre GPU for every image
• More private fine-tuning: more companies are training a private version on their own catalogue rather than using the generic public weights
• Video and 3D extensions maturing: the same underlying approach now feeds video and 3D preview tools, so one prompt can produce a still, a short clip, and a rough 3D asset
• Tighter integration inside design software: generation is increasingly a plugin inside tools like Photoshop or Figma rather than a separate app you switch to
• More attention on licensing and watermarking: as regulation catches up, provenance tags and clearer commercial licences are becoming standard rather than an afterthought
• Managed enterprise hosting: companies that don't want to run their own servers can now buy a managed version of the same open technology, getting some of the control without the maintenance
A few numbers worth knowing
Stable Diffusion's open model files have been downloaded tens of millions of times from Hugging Face alone, with several times that number across community platforms, which makes it the largest open-source ecosystem in image generation by a wide margin. On the pricing side, generating an image through the flagship large model now costs a few cents through the official API, with a lighter mid-tier version costing less again, keeping large-batch generation affordable even for smaller businesses.
Keeping half an eye on Stable Diffusion development trends 2027 is worth doing even if you're not technical yourself. It tells you when it's worth re-checking your own setup, and when a new version might quietly change the look of your output.
How Stable Diffusion Is Used for AI Image Generation in 2027
To really understand how Stable Diffusion is used for AI image generation in 2027, it helps to look at actual workflows rather than the feature list. Here's what businesses are doing with it day to day:
• E-commerce product photography: one hero shot of a product becomes five backgrounds and three lighting styles, instead of a reshoot for every new listing
• Ad testing at scale: agencies produce dozens of ad variations for A/B testing without booking a new shoot for each version
• Game and app prototyping: studios generate concept art, environment textures and character variations early on, bringing in an artist only to polish the picks that stick
• Architecture and real estate pitches: a floor plan sketch becomes a furnished render for a client meeting, without waiting on a 3D artist's schedule
• Retail personalisation: a shopper sees the same shirt shown on a body type and skin tone closer to their own, generated on the fly rather than picked from a fixed set
• Print-on-demand catalogues: large batches of unique pattern designs go out for merchandise without a designer working on each SKU individually
• Regional localisation: background signage, text, or cultural details in a marketing image get swapped for different markets without a full reshoot
Once you see how Stable Diffusion is used for AI image generation in 2027 across these industries, the setup effort most businesses put in at the start makes a lot more sense.
The Part Nobody Puts in the Demo Video
Most write-ups stop at the feature list. What actually decides whether this works for your business is how you handle the messy parts, the gaps, the contradictions, and the edge cases that only show up once you're running this at real volume.
· Gaps in your training photos show up as confident mistakes
If you fine-tune the model on your product photos but only have shots from one season, or one lighting setup, the model will still generate an image for a situation it's never actually seen, and it won't flag that it's guessing. You might get a coat with buttons added when the real one is a zip-up, or packaging text that looks fine at a glance but is unreadable up close. The model always produces something; it never says "I'm not sure about this one." That's exactly why an unnoticed gap in your training set can slip through until a customer or your own QA team catches it.
· Conflicting instructions get resolved quietly, not flagged
When a prompt combines instructions that partly pull against each other, say, "photorealistic" alongside a very stylised reference image fed through ControlNet, the model doesn't stop and ask which one you meant. It picks a compromise, and that compromise is often not what anyone actually wanted. Teams that skip a review step on batch output tend to learn this the expensive way, usually after fifty images have already gone out with a visible artifact in the same spot.
· Real-time decisions matter more than end-of-week reviews
Businesses generating images at real volume, live product photography, on-the-fly personalisation, need checks built into the moment an image is created, not just a review at the end of the week. That means an automatic filter checking resolution, checking that a face or logo wasn't distorted, before an image reaches a live storefront. Waiting to catch problems in a weekly batch review is too slow once the system is producing hundreds of images a day.
· Some categories are exceptions, and should be treated that way
Small text on packaging, hands, and tiny logos are still where this technology struggles the most, even with the improvements by 2027. A sensible workflow routes anything with visible text or a brand logo through a human check or a second pass, instead of trusting every output the same amount. Businesses that treat every image as equally reliable, without flagging the categories known to cause trouble, tend to see complaints cluster in exactly those categories.
· System behaviour changes under load
Running the model on your own hardware means performance depends on how many jobs are queued at once. A marketing team generating a hundred images before a launch can slow down a server another team relies on for a live feature. Separate queues, or extra cloud capacity during busy weeks, stop one team's rush job from blocking everyone else's.
Pro Tips
• Keep a short "known weak spots" list for your specific fine-tune (hands, tiny text, particular fabric patterns) and route those through manual review by default
• Lock the model version you use in production. An automatic update mid-campaign can quietly shift your output style without anyone noticing until the images look slightly off
• Save the seed number with every approved image, so you can regenerate the exact same result later if a client asks for a small tweak
• Run a monthly check comparing a sample of generated product images against real photos, to catch drift before it shows up in return rates
• Check the licence on any add-on model or checkpoint downloaded from a community site before using it commercially. Not all of them allow it
Key Takeaways
• Stable Diffusion gives a business ownership, privacy, and a lower cost per image at scale, in exchange for setup and maintenance work
• Closed tools like Midjourney, DALL-E and Firefly get you started faster, but keep you dependent on someone else's servers and pricing
• Most serious business use of Stable Diffusion in 2027 blends both: a closed tool for quick day-to-day content, an open fine-tuned pipeline for anything high-volume or brand-specific
• The biggest real-world risk isn't image quality, it's unnoticed gaps and unreviewed exceptions slipping into a live product page or storefront