A customer emails your support address at 9:40 on a Tuesday morning. Checkout keeps failing, she writes, and she has tried twice. Your team opens the admin panel and everything looks normal. The servers are running, the site loads, and nobody can say what's wrong, because nobody can see inside the part that broke.
That gap is what monitoring exists to close. In simple terms, it means collecting small measurements from your software all day long (how many requests arrived, how many failed, how long each one took) and keeping them so you can look back later. When it's set up well, the first warning comes from a graph instead of a customer.
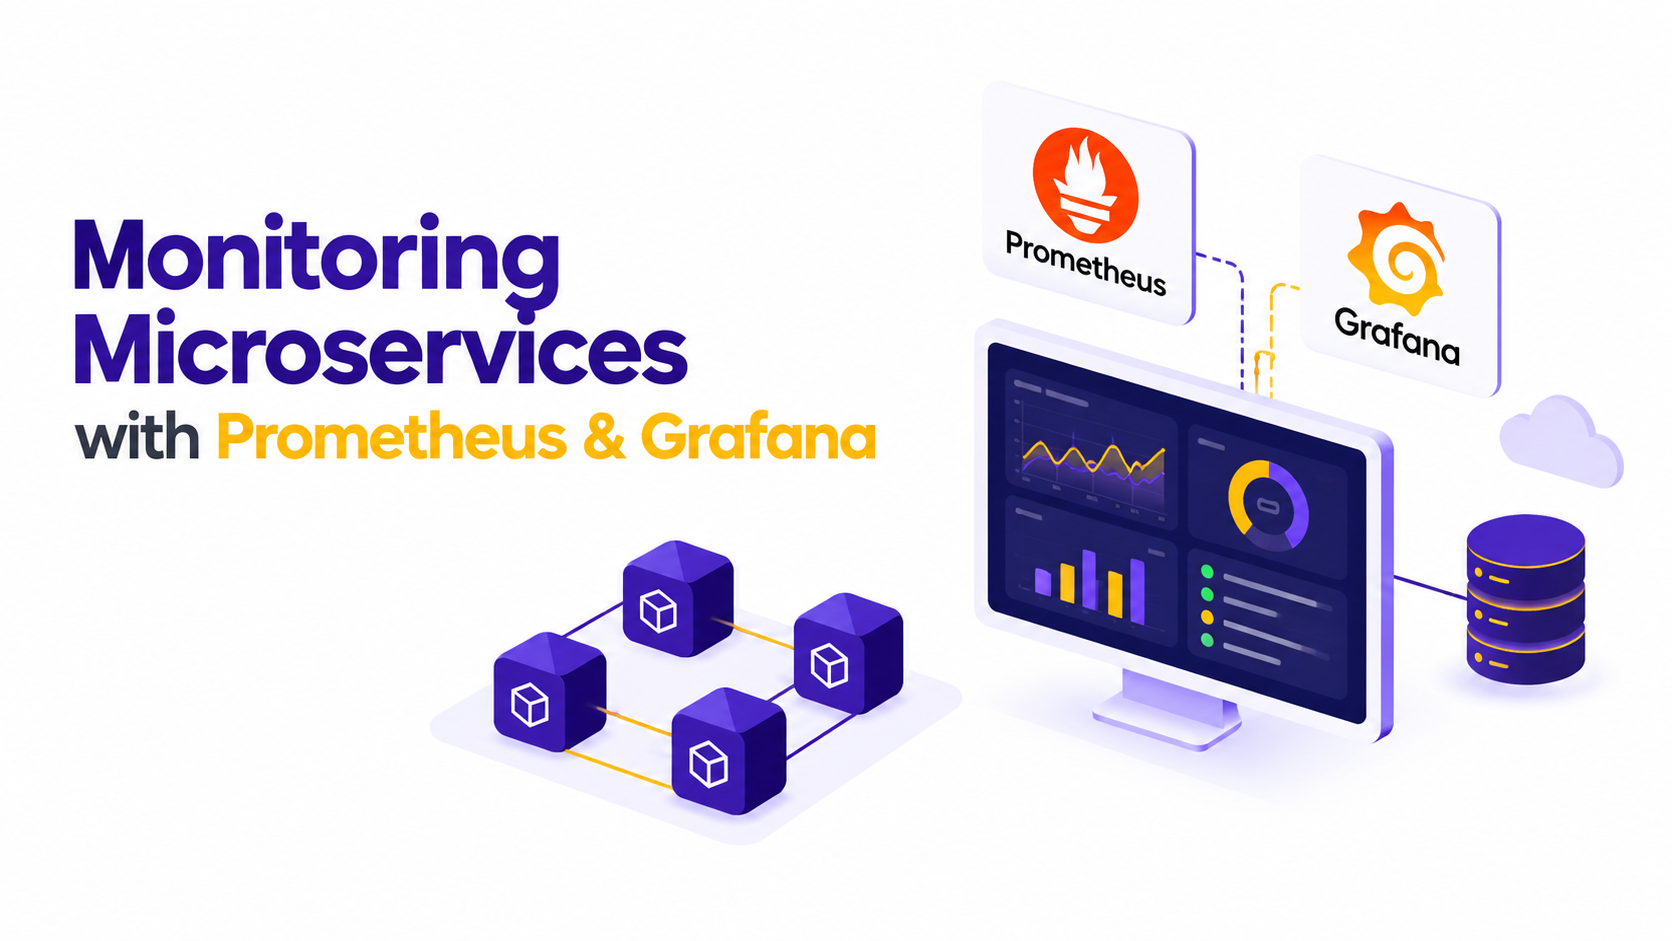
This guide covers one of the most common ways to do it. Prometheus collects and stores the measurements, and Grafana turns them into dashboards people can read. You don't need an engineering background to follow along. Technical terms get a short explanation when they first appear, and the messy parts of real life get their own space: missing data, graphs that disagree, and what happens when a system grows faster than expected.
Why microservices are harder to watch
An older-style application is one big program. If it breaks, you look at that program. A microservices setup splits the work into many small programs that talk to each other over a network. One handles logins, another handles payments, another sends emails. A single click from a customer can pass through six of them.
That design has real benefits. A team can change one piece without touching the rest, and a busy piece can be given more capacity on its own. The price is that failures become harder to locate. The payment service might be slow only because the database behind the inventory service is slow. If you watch only the payment service, you'll spend an hour looking in the wrong place.
Guessing gets expensive. ITIC's 2024 Hourly Cost of Downtime Survey, which polled more than 1,000 firms worldwide, found that one hour of downtime costs over $300,000 for more than 90% of mid-size and large enterprises. ITIC also points out that small businesses carry the same risk, even though their dollar losses are a fraction of that.
Good system monitoring answers three questions. Is something broken right now? Where is it broken? Was it already getting worse before it broke? Without stored history, you can only answer the first one.
What Prometheus and Grafana do
Prometheus is a free, open-source tool that collects numbers from your software and stores each one with a timestamp. It began at SoundCloud in 2012, after the company found that its older metrics tools couldn't handle its container-based setup. It joined the Cloud Native Computing Foundation (CNCF) in 2016 and graduated in August 2018, the second project to do so after Kubernetes.
Grafana is a separate free tool that draws charts. Torkel Ödegaard released it in January 2014, and it started as a fork of Kibana. Grafana doesn't keep your measurements. It asks other systems for data each time a dashboard loads, and it can combine results from several sources on one chart.
The two work well together because each has a narrow job. Prometheus is the record keeper and Grafana is the window you look through. A third piece, Alertmanager, handles who gets notified and when. The table shows how they divide the work, which is the foundation of Prometheus monitoring on most teams.
One more term is worth knowing: observability. It means being able to understand what's happening inside a system from what it reports. Three kinds of reports matter. Metrics are numbers over time. Logs are written records of events. Traces follow the path of one request across services. Prometheus handles metrics only, which is a deliberate limit and shapes how you pair it with other tools.
Who uses it: a snapshot
Before picking among observability tools, it helps to see what other teams run. Grafana Labs publishes an annual survey of practitioners. One caveat: the company's own 2024 report says its open-source-friendly community likely skews the results, so treat the numbers as a view of that community rather than of every business.
OpenTelemetry, mentioned in the table, is a newer open standard for collecting metrics, logs and traces. Prometheus 3.0, released on November 14, 2024 as the project's first major release in seven years, can take in OpenTelemetry metrics directly. The two are used side by side more often than as rivals, though that receiver handles metrics only.
How a number travels from your code to a chart
1. Your service publishes a page of numbers. Each service exposes a simple web page, usually at an address ending in /metrics, listing its current counts and timings. Libraries for most programming languages create this page. For software you can't change, such as a database or a Linux server, a small helper program called an exporter publishes the numbers instead.
2. Prometheus visits each page on a schedule. This visit is called a scrape. Because Prometheus does the fetching (the "pull" model), it notices right away when a service stops answering. It also records a built-in value called up for every target, 1 for a good scrape and 0 for a failed one. You get a basic health check without writing anything.
3. Prometheus stores what it collected. The data lands in a time series database on its own disk. The official documentation puts the average at 1 to 2 bytes per sample, which is small.
4. You ask questions in PromQL. That's the Prometheus query language. A question like "what share of checkout requests failed over the last five minutes?" becomes one short expression.
5. Rules watch the answers. If a rule's condition holds for long enough, Prometheus sends an alert to Alertmanager, which decides who hears about it.
6. Grafana draws the charts. It runs queries against Prometheus and shows the results as graphs, tables and gauges. Most people in a company only ever see this last step.
Every number Prometheus stores is one of four types:
• Counter: only goes up, such as total orders placed. Prometheus works out how fast it's growing, and a restart that resets it to zero is handled.
• Gauge: moves up and down, such as memory in use or jobs waiting in a queue.
• Histogram: sorts measurements into buckets, for example how many responses took under 0.1 seconds, under 0.5 seconds and under 1 second. Percentiles can be worked out from it, even across many copies of a service.
• Summary: similar to a histogram, but the percentiles are calculated inside the app, which makes them harder to combine across several copies of a service.
Each number also carries labels, which are tags such as service="checkout" or status="500". Labels let you slice one measurement by service, version or region. They also cause the most trouble at scale, which comes up later.
Pro tip. In your first week, stop one test service on purpose and watch up drop to 0 in Prometheus. Seeing a failure appear on screen once makes the alert rules you write later easier to trust.
Setting it up for the first time
Start with one service and one dashboard. It's easier to learn the tools on something small, and a single working example is simple to copy to the next service.
The order of work looks like this. Run Prometheus (the project provides ready-made packages and container images, and its web page opens on port 9090 by default). Add a metrics library to one service so it publishes a /metrics page. Tell Prometheus where that page is. Run Grafana (port 3000 by default), add Prometheus as a data source by entering its address, then build or import a dashboard.
Telling Prometheus where to look takes a few lines in its configuration file. This example scrapes a service called orders every 15 seconds:
global:
scrape_interval: 15s
scrape_configs:
- job_name: "orders"
static_configs:
- targets: ["orders:8080"]
A fixed list of addresses works for a handful of services. It stops working when containers appear and disappear every few minutes. For that case Prometheus supports service discovery: it asks the platform (Kubernetes, for example) which services exist right now and starts scraping new ones automatically. Teams on Kubernetes often install a bundle such as the kube-prometheus-stack Helm chart, which sets up Prometheus, Alertmanager, Grafana and a starter set of dashboards together.
A first round of Prometheus monitoring for a single service gives you request counts, error counts and response times. That's enough to answer the question from the opening scenario.
What to measure
The hard part isn't installation. It's choosing which numbers matter, because one service can publish thousands. Three short checklists have become standard, and they overlap.
• The four golden signals, from Google's site reliability engineering book: latency, traffic, errors and saturation.
• The RED method, from Tom Wilkie (now CTO of Grafana Labs): rate, errors and duration. It suits services that answer requests.
• The USE method, from Brendan Gregg: utilization, saturation and errors. It suits machines and resources such as CPU, disk and memory.
For a checkout service, the common set looks like this:
Duration deserves care, because an average can hide the pain. Here's a made-up example. A service answers 99 requests in 100 milliseconds and one request in 8 seconds. The average works out to about 180 milliseconds, which looks fine, while one customer in a hundred waits 8 seconds. The 99th percentile is the time that 99% of requests beat, and it shows the problem straight away. That's the reason histograms are worth their small extra setup.
Business numbers belong here too. Orders per minute, sign-ups and failed payments can be measured the same way, and the 2026 Grafana Labs survey found that half of organizations now use their monitoring setup for business-related metrics. Basic system monitoring of CPU and memory still has a place, but it works best underneath the request-level numbers.
Building Grafana dashboards people read
A dashboard fails when nobody opens it. The usual cause is trying to show everything on one screen. A few habits help:
• One dashboard per question. "Is checkout healthy?" gets its own screen, and "why is the database slow?" gets another.
• Overview first. Request rate, error rate and response time go at the top, with detail underneath.
• Use variables. Grafana can add drop-downs for service, environment or version, so one dashboard serves every service instead of 30 near-identical copies.
• Mark deployments on the graphs. A thin vertical line at each release explains many sudden changes.
• Let Grafana pick the rate window. Its built-in $__rate_interval variable chooses a window long enough for your scrape interval, which helps avoid empty or jumpy graphs.
The Grafana integration with Prometheus is a built-in data source, so connecting the two takes an address and a click. The more useful work is deciding who each dashboard is for. Developers want detail. A founder or an office manager wants three numbers and a color: orders per minute, error rate, and whether anything is red. Both views can come from the same Prometheus data.
Alerts that don't cry wolf
Dashboards help when someone is looking. Alerts are for when nobody is. The 2026 Grafana Labs survey found that alert fatigue was the biggest single obstacle to faster incident response, named by 30% of respondents and nearly double the next most common answer. Too many alerts teach people to ignore all of them. These settings keep the count down:
• Alert on symptoms customers feel, such as error rate or slow checkout, instead of every possible cause such as high CPU on one machine.
• Add a waiting period. Prometheus alert rules have a for setting, so a condition must hold for, say, five minutes before the alert fires. A one-minute blip then stays quiet. Grafana calls the same idea a pending period.
• Let Alertmanager group alerts. The official documentation describes a case where hundreds of service instances can't reach one database and each sends its own alert. Grouping turns them into one notification.
• Use inhibition and silences. Inhibition mutes smaller alerts when a bigger one is already firing. A silence mutes an alert for a set time, such as during planned maintenance.
• Run more than one Alertmanager. It supports clustering for high availability. The documentation says not to put a load balancer between Prometheus and the Alertmanagers, and to point Prometheus at every instance instead.
Prometheus rules plus Alertmanager is one path. Grafana has its own alerting too, and a single Grafana rule can query several data sources. Either works, but give each alert one home. Two systems watching the same thing with slightly different settings produce duplicate pages and arguments about which one is right. A good Grafana integration can still show the current alert list on a dashboard, so people see warnings next to the graphs.
Pro tip. Write the first action into the alert text. "Checkout error rate above 5% for 5 minutes. Check recent deploys, then database connections." Someone half awake at 3 a.m. needs a starting point more than a diagnosis.
When the data has gaps
Real systems drop data. A network hiccup, a restart or a busy server can make a scrape fail and leave a hole in the graph. Knowing how Prometheus and Grafana treat holes saves you from false alarms and, worse, false calm.
A failed scrape
When a scrape fails, up drops to 0 for that target and its graphs show a gap. Prometheus also marks a series as stale when it stops appearing, so a dead service's numbers don't linger as if they were current.
A scrape interval that's too long
When you ask Prometheus for the latest value, it looks back up to five minutes by default. A series scraped less often than that vanishes from the answer between scrapes. A PromCon 2017 talk on staleness by Brian Brazil, a longtime Prometheus developer, puts the practical limit at around two minutes, since you have to allow for one failed scrape.
Short-lived jobs
A nightly backup job may finish before Prometheus ever visits it. Such jobs can push their results to a helper called the Pushgateway, which Prometheus then scrapes. The catch is that the Pushgateway deliberately has no expiry for pushed values, so a job that stopped running months ago can still show its last success. The official instrumentation guide says the key metric for a batch job is the time of its last success, which you can alert on when it gets too old.
Silence that looks like health
A graph with no line and a graph sitting at zero look alike at a glance, yet they mean different things. A new service that has never had an error may publish no error series at all, so a query dividing errors by requests returns nothing instead of 0%. The instrumentation guide suggests exporting a default value of 0 for any series you know will exist.
Grafana alert rules have to decide what "no data" means. You can set it to Alerting, Normal, Error or Keep Last State. Keep Last State quiets short data source problems, but Grafana's own documentation warns that it may not suit cases where strict monitoring is critical. A related setting controls how many checks in a row can come back empty before Grafana treats an alert as resolved. For a customer-facing service, an alert on missing data is usually worth having.
When the signals disagree
Two numbers that don't match are normal. The skill is knowing which one to trust for which decision.
The saved query mentioned in the third row is called a recording rule. Prometheus calculates it ahead of time and stores the result as a new series. Using one for both the dashboard and the alert keeps them consistent, and it makes dashboards load faster too.
Making decisions in real time
Monitoring feels instant, but it has delays built in, and each one is a trade-off. Take a typical alert with example settings. Prometheus scrapes every 15 seconds. A rule checks the data on its own schedule, often once a minute. The rule waits five minutes before firing. Alertmanager then pauses briefly to group related alerts before sending. Add it up and a real problem can take more than five minutes to reach a phone.
Shorter delays mean faster warnings and more false alarms. Longer delays mean calmer nights and slower response. Match the setting to the damage a delay would cause: a payments service might justify a two-minute wait, while an internal reporting tool can wait fifteen. Faster scraping also costs storage, since halving the interval doubles the samples.
Some decisions can be automated. Autoscalers on Kubernetes can add capacity based on a Prometheus query (KEDA is one tool that does this), and teams often compare error rates between the old and new version during a release to decide whether to roll back. Automation raises the stakes on data quality, because a gap or a stale number can trigger the wrong action. Give any automated decision a safe default for when data goes missing.
How it behaves under pressure and at scale
Cardinality, the quiet cost
Every unique combination of labels is its own time series. Take a request counter with a method label (4 values), a status label (5) and an endpoint label (20). That's 400 series for each copy of the service. Add a user ID label with 10,000 users and it becomes 4,000,000. These numbers are an illustration, but the multiplication is real. Memory and disk use in Prometheus follow the number of series, not just traffic. The official guidance says a metric whose label combinations could pass 100 deserves a second look. Detail at the level of single users belongs in logs or traces.
Storage arithmetic
The documentation gives a simple formula: retention time in seconds, times samples per second, times bytes per sample. Try 100,000 active series scraped every 15 seconds with the default 15-day retention. That's about 8.6 billion samples, or roughly 9 GB at 1 byte per sample and 17 GB at 2 bytes. The docs also suggest setting the retention size to at most 80 to 85% of the disk, because compaction needs temporary room.
One server is one server
Prometheus's local storage isn't clustered or replicated, so it's limited to one machine's capacity and durability, and the documentation says to manage it like any single-node database. Teams usually grow in steps:
Grafana Labs announced Mimir 3.0 on November 5, 2025, describing it as a horizontally scalable, Prometheus-compatible metrics backend. Prometheus also has an agent mode, started with the --agent flag, that only collects data and forwards it elsewhere.
Watching the watcher
During an outage more people open dashboards, and heavy queries pile onto the same server that's collecting data. Keep refresh rates sensible and use recording rules for expensive queries. Alert on Prometheus's own numbers too, such as how long scrapes take. Many teams also add an alert that always fires and send it to an outside service. When it stops arriving, the alerting chain itself is down. Alertmanager is built to lean toward sending duplicates over missing an alert if cluster members lose contact, which is the right bias for a pager.
What it costs and who does the work
Prometheus and Grafana are free to download. The bill shows up as servers, storage and people's time. The 2026 Grafana Labs survey is useful here. Half of respondents use SaaS for observability in some capacity, up from 43% the year before, and cost was the top tool-selection criterion for the third year running at 65%, followed by ease of use at 49%. Teams that run everything themselves were most likely to name complexity as their top concern, while SaaS users more often pointed to cost.
For a small team, a sensible path is to start self-hosted on one server, learn what you actually need to measure, and then decide whether running it yourself is worth the hours. If you're comparing observability tools as a business owner, three questions help. Who is on call when the monitoring itself breaks? How long is history kept? How does the bill grow when we add services?
Mistakes teams make early
• Tracking everything. Start with rate, errors and duration, and add more when a real question needs it.
• Putting user IDs, session IDs or full URLs into labels.
• Alerting on causes instead of symptoms.
• Reading "no data" as "no problem."
• Leaving all history on one local disk with no plan for backups or growth.
• Building dashboards and alerts with no named owner. Treat system monitoring like any other product that someone is responsible for.
Key takeaways
• Prometheus collects and stores numbers, Grafana shows them, and Alertmanager decides who is told.
• Start with rate, errors and duration for one service, and watch the 95th and 99th percentiles instead of averages.
• Missing data needs its own handling. An empty graph is not a healthy graph.
• Labels multiply series. Keep them few and never use user IDs.
• A single Prometheus server has hard limits. Plan for a second server or remote storage before you need it.
Conclusion
Monitoring microservices comes down to a loop. Collect a few meaningful numbers, store them cheaply, show them where people will look, and alert only when a person needs to act. Prometheus and Grafana cover that loop well, and both are free to try. Start with one service, learn how gaps and conflicting numbers behave on your own data, and add structure as you grow. Done this way, Prometheus monitoring turns into quiet background work, and the next 9:40 Tuesday email arrives after the alert instead of before it.