A shopper in Sydney taps "Pay now" on an online store. The store's servers sit in a data center in northern Virginia, about 15,000 kilometers away. Light inside a fiber optic cable moves at roughly two thirds of its normal speed, so one trip there and back takes at least 150 milliseconds before the server does any work.
That sounds small. But loading a page is never one trip. The browser has to find the server's address, open a connection, agree on encryption, ask for the page, then ask for the scripts, images and data that page needs. Add those trips together and the shopper can wait a second or more watching a spinner. Some of them give up and leave.
Faster code won't fix this. The distance is the problem, and the only real fix is to move the work closer to the person using the app.
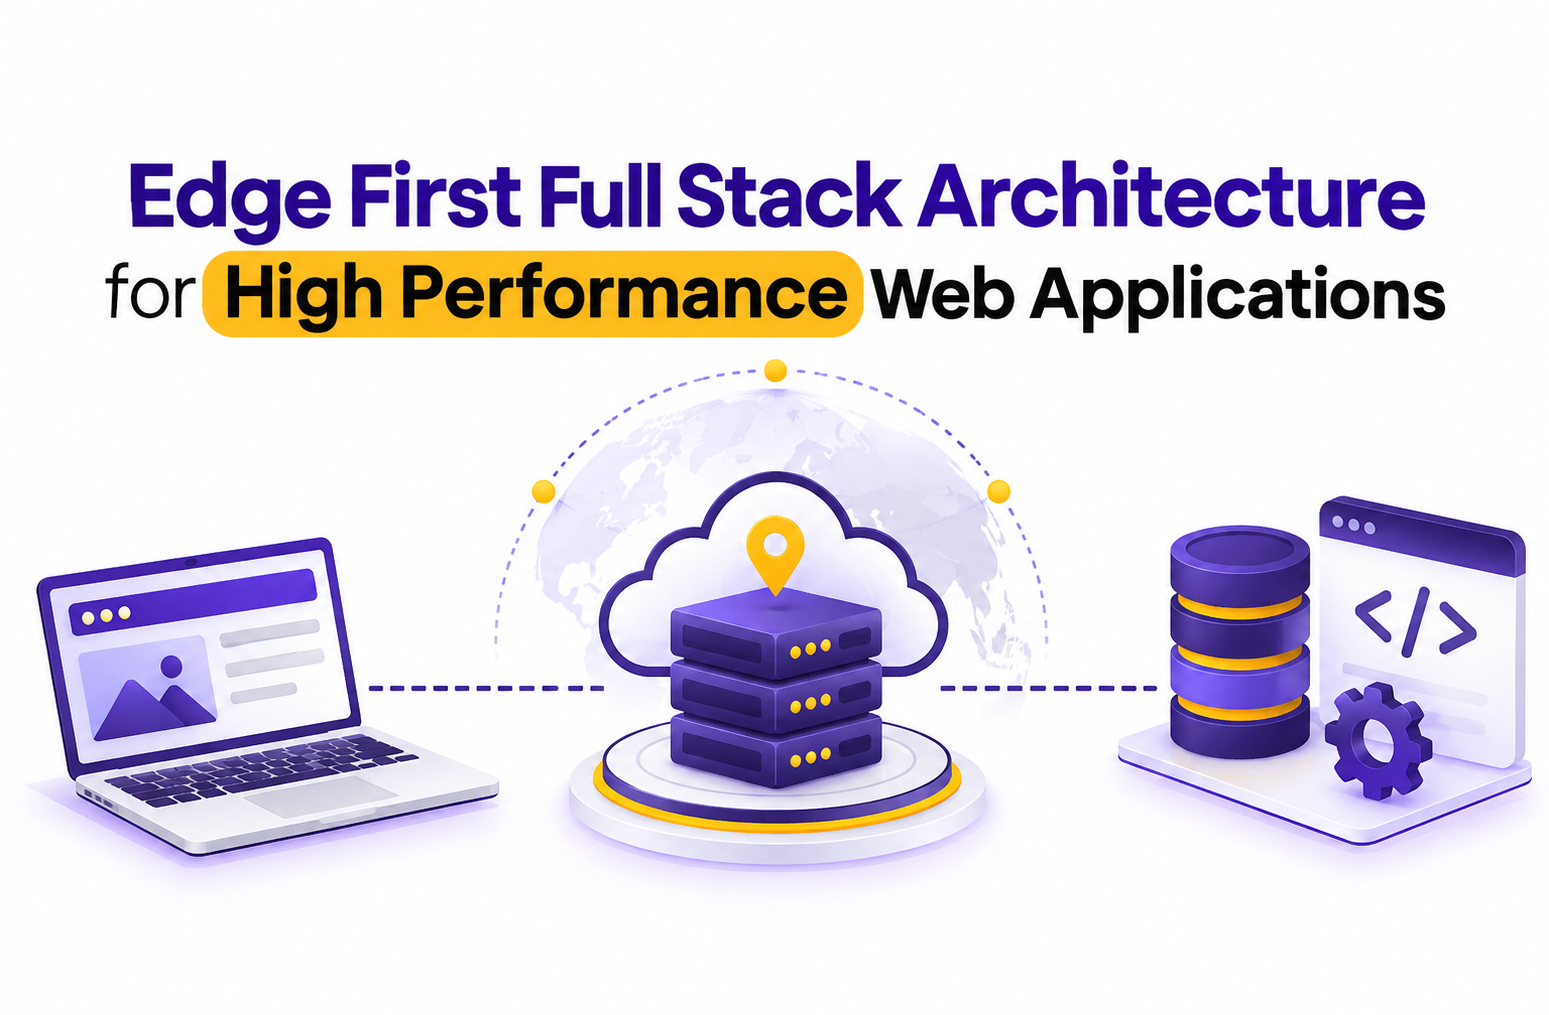
That is the idea behind edge first full stack architecture. This guide covers what it means, how the pieces fit together, where it gets messy (mostly around data), and how a small team can adopt it step by step. You don't need to be a developer to follow along.
First, what "the edge" actually means
Engineers talk about the internet as having a center and an edge. The center is the big data centers run by cloud companies, usually in a handful of regions. The edge is the much larger set of smaller server locations spread across hundreds of cities, close to where people live and work.
You've used the edge for years without knowing it. When a streaming show starts right away or a news site's photos appear quickly, those files most likely came from a nearby server, not from the company's main data center. That nearby network is called a CDN, short for content delivery network. A CDN keeps copies of files in many cities so each visitor gets them from the closest one.
For a long time, CDNs only handled the easy stuff: images, videos, and files that look the same for every visitor. Anything personal, like your cart, your account page or your search results, still had to travel back to the main server. Engineers call that main server the origin.
That changed when CDN companies began letting businesses run their own code on edge servers. Now the edge can do more than hand out stored files. It can check whether you're logged in, pick the right language, build parts of a page, and decide where to send a request. This shift is what made edge computing for web applications practical for ordinary businesses as well as giant platforms.
A bakery version of the same idea
Think of a bakery chain. In the old model, every cake is baked in one central kitchen and driven to customers across the country. In the edge model, small kitchens in every neighborhood handle most orders on the spot.
The central kitchen still keeps the recipes, the master stock list and the money. But a customer who wants a regular loaf never waits for a truck.
What "edge first" changes about how you build
Plenty of companies already put a CDN in front of their app. That alone doesn't make them edge first. The difference is the default question the team asks when it builds a new feature.
In a traditional full stack development architecture, the default answer is "the server will handle it." The front end (what you see in the browser), the back end (the rules and logic) and the database all assume they live in one place. Speed tricks get added later, if at all.
An edge first team asks something else: "Can this run near the user?" If yes, it goes to the edge. If it truly needs the central database or heavy processing, it goes to the origin. The edge becomes the starting point, and the origin handles the exceptions.
Here's how the work usually gets split.
What usually runs where
The building blocks, explained without the jargon
If you know a classic full stack development architecture, you'll recognize each layer below. What changes is where each one lives.
1. The CDN layer
This is the base. Static files sit in edge locations around the world. A CDN-based app architecture treats this layer as the front door for every request, including the ones that ask for personal data. Each visitor reaches the nearest edge location first, and that location decides what happens next.
2. Small pieces of code that run near the user
These are short programs that run on edge servers whenever a request arrives. People call them serverless edge functions. "Serverless" sounds odd, because there are servers involved. It only means you don't manage them yourself. You upload the code, and the provider runs it in whichever city the request lands.
They're good at quick jobs. Think reading a cookie, redirecting a visitor, adding a security header, or choosing which version of a page to show. Most start in a few milliseconds. Older cloud functions could take hundreds of milliseconds, sometimes more than a second, to wake up. That wake-up delay is called a cold start.
There are limits, and they matter. Providers cap how much processing time each request gets, and many don't support every feature a normal server does.
3. Building pages close to the visitor
Every web page has to be turned into HTML, the code a browser reads to draw the page. That step is called rendering. It can happen in the visitor's browser, on a central server, or at the edge.
Edge rendering means the HTML gets built in the edge location nearest the visitor. People see real content sooner, because the page arrives mostly ready and didn't have to cross an ocean. Frameworks such as Next.js, Nuxt, SvelteKit and Astro all support some version of it.
The smart move is mixing approaches on one page. A product page might have a shared part (photos, description, reviews) that's built once and cached, plus a small personal part (your cart count, items you viewed) filled in at the edge or in the browser. Some frameworks call this streaming. You send what you can right away and fill in the rest as it becomes ready.
4. The origin and the main database
The origin doesn't go away. It still holds the main database, runs payments, sends emails, builds reports and does anything heavy. In a good setup, it simply gets far fewer requests than before, because the edge answers most of them. That can cut server bills and keep the origin calm during busy periods.
5. Storage at the edge
Newer tools add small storage systems at the edge too. These include key-value stores (think of a giant lookup table of names and values), databases that copy themselves to many regions, and caches. They let the edge answer more questions without calling home. They also bring the hardest problems in this whole approach, which we'll get to shortly.
Why the speed is worth the effort
Those first two figures come from "Milliseconds Make Millions," which tracked real mobile sites for 30 days at the end of 2019. When pages got 0.1 seconds faster across four speed measures, retail conversions rose 8.4% and travel conversions rose 10.1%.
One caveat: Google commissioned that study, and Google benefits when the web gets faster. Treat the exact percentages as a guide, not a promise. For high performance web applications, though, the lesson holds. Small delays repeat on every page of a visit, and they add up.
The Cloudflare figure also comes from the company itself, so read it as a vendor claim. What it shows is how dense these networks have become.
The wider market is growing as well, though nobody agrees on its size. That disagreement teaches something useful.
Same year, very different numbers: 2025 edge computing market estimates
That's a tenfold gap for the same year. The reason is definition. Some firms count only edge software and services. Others include hardware such as factory sensors, telecom equipment and on-site servers. Before you quote any of these in a pitch deck, check what the report actually counts. Market size tells you the trend is real. It tells you very little about whether edge computing for web applications suits your product.
Three common setups, side by side
Most web businesses fall into one of three patterns. Here's how they compare.
Single server vs. CDN in front vs. edge first
Look closely at the middle column. Plenty of businesses get most of the benefit from a well set up CDN alone, and never need to go further. Going fully edge first makes sense when your users are spread across countries and every fraction of a second shows up in sales. That's the territory of high performance web applications, where the extra effort pays for itself.
The hard part is data
Moving code to the edge is fairly easy. Moving data is not.
Your code can run in 300 cities. Your database usually lives in one. When an edge function needs fresh data, it still has to call home, and that trip brings back the delay you were trying to remove. Each workaround creates its own problem.
Data gaps: when the edge doesn't know enough
An edge location only knows what it has been told. If a visitor in Lagos asks for a product nobody in Lagos has viewed recently, the local cache is empty. That's a gap, and the edge has to fetch from the origin.
Gaps also show up in quieter ways. A new product goes live, but some edge locations keep serving the old catalog page for another ten minutes. A customer changes their delivery address on a laptop, then opens the app on their phone through a different edge location that hasn't heard about the change yet.
A few habits help:
▪ Decide how old each type of data is allowed to be. A blog post can be an hour old. A stock count should be seconds old. A bank balance shouldn't be cached at all.
▪ Use purge tools to clear specific cached pages the moment something changes, instead of waiting for them to expire.
▪ When the edge can't find what it needs, fall back to the origin quietly. A missing local copy should never turn into an error page.
Conflicting signals: when two places disagree
Some setups copy the database to many regions so reading is fast everywhere. That works well until two people change the same thing at the same moment in different places.
The classic case is the last item in stock. A shopper in London and a shopper in Singapore both see "1 left" and both press buy within the same second. Each nearby copy says yes. You've now sold one item twice.
There's no magic fix, only trade-offs:
▪ Send every write that must never conflict (stock, payments, seat bookings) to one central database. Reading can happen anywhere. Writing these stays in one place.
▪ Where a small mismatch is harmless, like a likes counter or a view count, let each region count on its own and add the totals later.
▪ Choose honest wording. "Only a few left" is safer than "1 left" when your numbers might be a second behind.
Conflicting signals come from outside your database too. A visitor's location says Germany, their browser language says Spanish, and their saved account says India. Which currency should the page show? Write the rule down before anyone builds it. A clear order (saved preference first, browser setting second, location last) prevents strange behavior that's painful to trace later.
Real-time decisions: what the edge should and shouldn't decide
The edge is a great place for quick calls that don't need the full picture. Is this request from a known bad bot? Is this login token valid and unexpired? Should this visitor see version A or version B of a page? Is this feature allowed in the visitor's country yet? Each question can be answered in a few milliseconds using information the edge already has, which is exactly the work serverless edge functions were built for.
Decisions that depend on the latest state of your business belong at the origin. Approving a refund, confirming a payment, applying a coupon with a usage limit. If edge code guesses wrong on one of these, someone loses money.
Here's a simple test. If this decision is wrong for a few seconds, does anyone get hurt? If not, the edge can handle it. If yes, send it home.
Exceptions and odd cases that catch teams out
▪ Caching a personal page by mistake. If a page showing someone's name gets cached and served to the next visitor, you have a privacy incident. Mark personal responses as "do not cache" by default, and turn caching on for each page deliberately.
▪ Running out of time. Edge code has strict limits on how long it can work per request. A function that's fine with ten items in a cart may hit the limit with 300. Test with realistic worst cases as well as typical ones.
▪ Missing features. Some code libraries expect a full server with a hard drive, and they break at the edge. Check this before you commit to a library.
▪ Data location laws. Rules such as Europe's GDPR can limit where personal data is processed or stored. When code runs everywhere, personal data may pass through places you didn't plan for. Most large providers let you keep certain work inside chosen regions.
▪ Wrong location guesses. Edge servers guess where a visitor is from their network address. VPN users, office networks and travelers often show up in the wrong country, so always let people change what you guessed.
▪ Clock surprises. A sale that "ends at midnight" ends at different moments in different places unless you store every time in one standard time zone.
How the system behaves under pressure
An edge setup copes well with spikes, if a few things are in place.
The flash sale
Say a store emails a discount to 400,000 subscribers at 10 a.m. Within minutes, tens of thousands of people arrive at once. With a single server, pages slow to a crawl and checkout starts timing out.
In an edge first setup, product pages are already cached in hundreds of cities, so most visitors never touch the origin. Pages built through edge rendering reach shoppers quickly even while the crowd grows. The origin only deals with carts and payments, which is a far smaller load.
The stampede
There's a well known failure here. If a popular cached page expires at the same moment everywhere, many edge locations ask the origin for a fresh copy at once. The origin, which was relaxed a second earlier, suddenly gets flooded. Engineers call this a thundering herd.
Two settings prevent it. The first lets the edge keep showing the slightly old page while it fetches a new one in the background (often labeled "stale while revalidate"). The second, request collapsing, merges many identical requests into a single trip to the origin. Most CDNs offer both. Check that they're switched on.
Too many database connections
A traditional database expects a small, steady number of connections from a few servers. Edge code is the opposite: thousands of short-lived copies, each wanting its own connection. At scale this can hit the database's connection limit and take everything down, even when traffic is normal.
The usual fix is a connection pooler. It's a middle layer that keeps a small number of real connections open and shares them across many requests. Some database providers also offer drivers that talk over ordinary web requests, which suits edge code much better.
When the edge provider has a bad day
Edge networks are very reliable, but not perfect. On June 8, 2021, a software bug at Fastly knocked large parts of the web offline for close to an hour. On November 18, 2025, Cloudflare had a global outage lasting roughly three hours, after an automatically generated settings file grew too large and crashed its traffic software. Sites such as X and ChatGPT went down with it.
When everything sits on one provider, that provider's outage becomes yours. This is the main weak spot of a CDN-based app architecture, and it's worth planning for. Keep a simple "we'll be right back" page hosted somewhere else, know how to switch your domain settings quickly, and if your revenue justifies it, set up a second CDN you can route traffic through.
How costs behave as you grow
Edge platforms usually charge per request and per slice of processing time. At low traffic this is often cheaper than running servers all day. At very high traffic, or when functions do heavy work, bills can climb fast. A bot attack sending millions of requests can also run up costs if it isn't blocked early. Set spending alerts on day one.
When edge first is the wrong choice
This approach isn't for everyone. Skip it, or wait, if any of these sound like you:
▪ Your users are mostly in one country, close to your server. The distance problem barely exists for you.
▪ Your app is an internal tool for a team of 50 people. The speed gain won't justify the extra moving parts.
▪ Most of your work is heavy processing, like video editing, large reports or training AI models. That belongs in central data centers with powerful machines.
▪ Your data rules require everything to stay in one location, and your provider can't promise that.
▪ You're a two-person team shipping a first product. Win customers first. A good CDN in front of a simple server will carry you a long way.
There's nothing second-rate about the middle option. Many fast, profitable sites run on one server and a well tuned CDN, and they'll never need more. Edge computing for web applications earns its place when distance is costing you customers, and not before.
A step-by-step path to adopting it
You don't rebuild everything at once. Each step should pay for itself before you take the next.
1. Measure first. Find out how fast your app is today for users in different countries. Real visitor data from your analytics beats tests run from your own office.
2. Put everything behind a CDN. Cache images, scripts and style files. This step alone often brings the biggest early gain.
3. Cache whole pages where the content is shared. Product pages, blog posts and landing pages are good candidates. Set a clear age limit for each.
4. Move small decisions to the edge. Start with redirects, security headers, bot filtering and language selection, since these carry little risk. This is where serverless edge functions first earn their keep.
5. Try edge rendering on one busy page. Compare speed and conversions against the old version before you roll it out further.
6. Bring data closer only where the numbers justify it. Add edge caches or read-only copies for data that's read often and changes rarely. Keep important writes central.
7. Plan for failure. Set up monitoring from several regions, spending alerts and a fallback page.
What changes for different people on your team
Moving to edge first full stack architecture affects more than the engineers.
Who notices what
For developers in particular, the shift is less about learning new tools and more about a new habit of thinking. A sound full stack development architecture for the edge starts every feature with two questions: where should this run, and how stale can its data safely be?
Where this leaves you
Speed on the web is mostly a geography problem. A well written app on a single server will still feel slow to someone on the far side of the world, because each request has to travel there and back several times.
Edge first design deals with that at the source. It puts files, quick decisions and much of the page building in hundreds of locations near your users, and keeps the central server for work that needs a single, trusted copy of the data. For high performance web applications with a global audience, that combination is hard to beat.
It's still a design choice with real costs. Data freshness becomes something you plan for instead of something you assume. Testing gets harder, and bills behave differently. Teams that do well with edge first full stack architecture move one step at a time, measure every change, and keep the money side of the app firmly in one place.
If your users are spread out and your revenue depends on how fast your pages feel, start with step one this week. Measure how your app performs in the countries you care about. The numbers will tell you how far down this path a CDN-based app architecture needs to take you, and whether you need more than that.