On a Monday morning, a sales manager opens the company dashboard and sees zero orders for Sunday. Nobody panics yet. Someone checks the store, and orders did come in. The problem sits further back. A nightly script was set to pull order data at 2:00 a.m., but the export from the payment system ran late that night and finished at 2:20. The script found an empty file, loaded nothing, reported "done," and the dashboard trusted it.
This kind of quiet failure is common in companies that run data jobs as a pile of scheduled scripts. None of the scripts know about each other, so when one step is late or broken, the next step runs anyway.
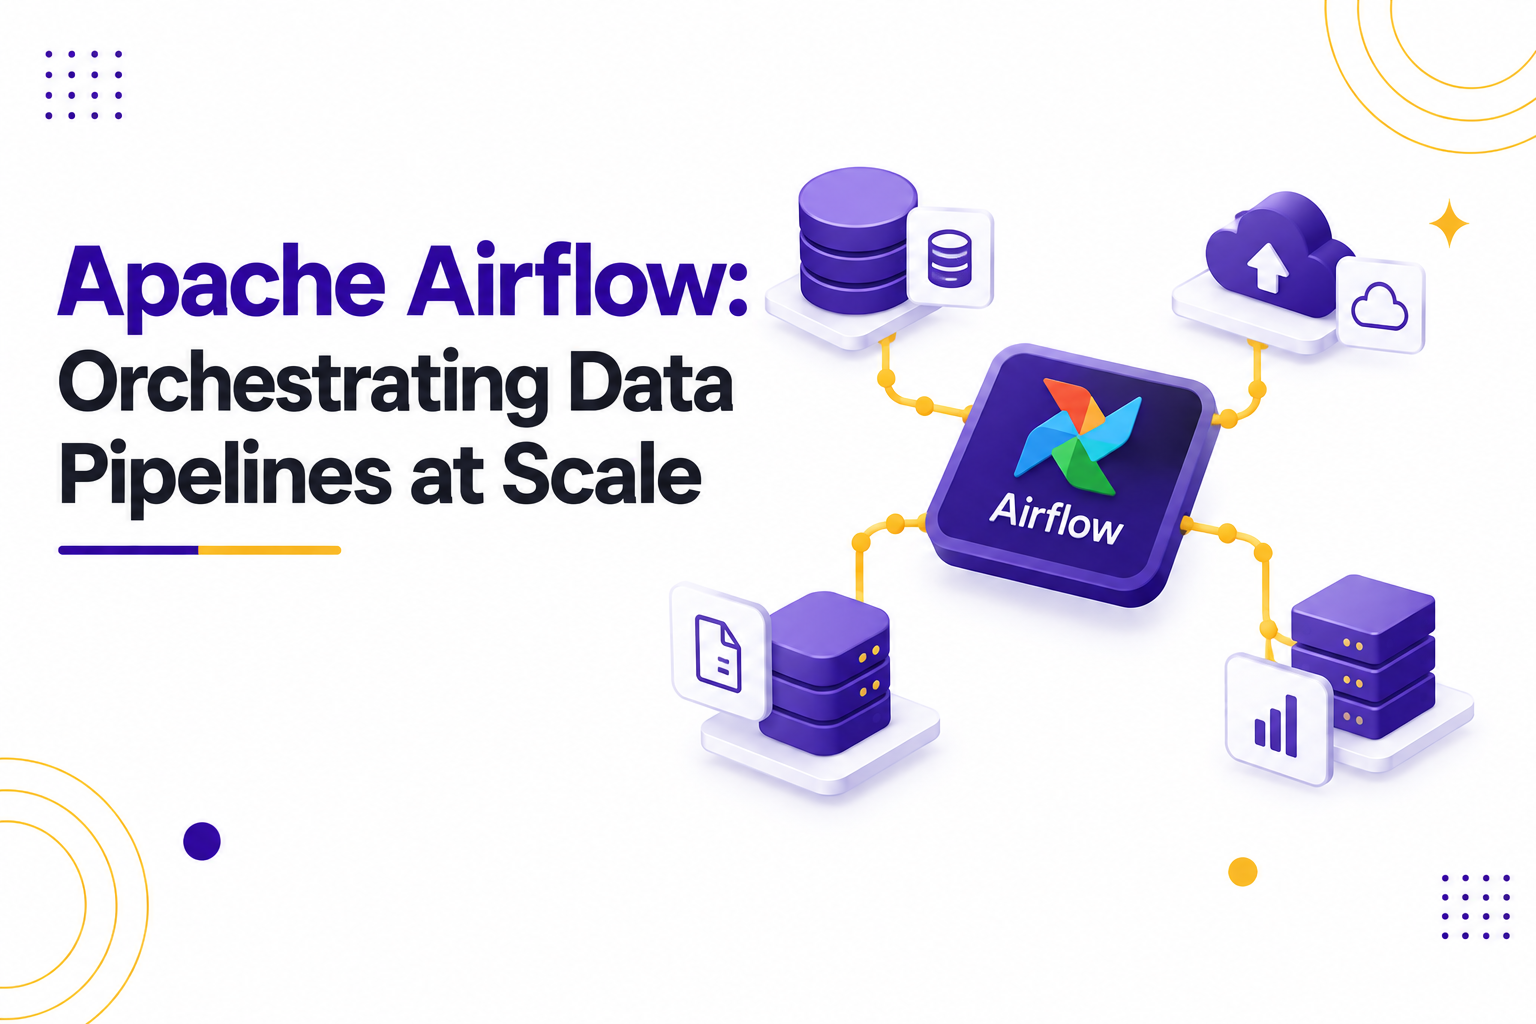
Apache Airflow was built for exactly this mess. It lets a team describe the whole chain of steps, the order they must run in, what each step depends on, and what should happen when something fails. That job has a name: data pipeline orchestration. This practical guide explains what Airflow does, how it works under the hood, where it struggles, and how it behaves when the number of pipelines grows from five to five thousand.
What Airflow actually does
Think about the person in a busy restaurant kitchen who calls out orders. They don't cook. They make sure the steak starts before the fries, that no plate leaves without its sauce, and that someone notices a stuck dish. Airflow plays that role for data work. In most setups it doesn't transform data itself. It tells other tools when to act, waits for them, checks the result, and decides what comes next.
You describe a workflow in Python. Airflow calls each workflow a DAG, short for "directed acyclic graph." The name sounds heavy, but the idea is simple:
▪ Directed means each step points to the step that follows it.
▪ Acyclic means the chain never loops back on itself, so a job can't end up waiting on itself forever.
▪ Graph means the steps can branch and merge, like a family tree, instead of running in one straight line.
Each step inside a DAG is a task. A task might download a file, run a SQL query, call an API, or send a Slack message. Airflow tracks every task through states such as queued, running, success, failed, and skipped, and shows each run as a grid of colored boxes in its web interface.
Here is what a small DAG looks like in Airflow 3:
Even if you don't write code, two lines matter here. The schedule runs this once a day. The retries setting tells Airflow to try extraction three more times before calling it a failure, so a brief network hiccup doesn't kill the whole run.
A short history, and where things stand in 2026
Airflow started inside Airbnb in 2014, created by engineer Maxime Beauchemin to manage the company's growing set of data jobs. It joined the Apache Software Foundation's incubator in 2016 and became a top-level Apache project in January 2019.
Release timeline at a glance
One date matters for anyone still on an older setup. According to the project's official version life cycle page, open-source Airflow 2 reached end of life on April 22, 2026. It no longer receives security patches or bug fixes. Teams still running it carry that risk until they upgrade.
The numbers behind the project
Airflow by the numbers
A note on sources: Astronomer sponsors the annual survey and sells a managed Airflow product, so it has a stake in Airflow's growth. The raw survey responses are published for anyone to check.
The wider market is harder to pin down, and the research firms don't agree. Grand View Research projects the global data pipeline tools market will reach about USD 48.3 billion by 2030, growing 26.8% a year from 2025. Global Industry Analysts puts the 2024 market at USD 13.0 billion and forecasts USD 54.2 billion by 2030. TechSci Research is far more cautious: USD 7.1 billion in 2023, rising to about USD 22.9 billion by 2029. The firms define "data pipeline tools" differently, which explains much of the gap. What every estimate shares is double-digit yearly growth. Grand View Research also found that ETL-style pipelines held the largest share by type in 2024, at roughly 39%.
The moving parts, explained simply
Knowing the parts of Airflow makes the later sections on failure much easier to follow. A deployment has a handful of components that talk to each other.
▪ The DAG processor reads your Python files and turns them into workflow definitions Airflow can understand. In Airflow 3, this runs as its own separate service.
▪ The scheduler is the brain. It checks which DAG runs are due, which tasks have their dependencies met, and which tasks can be sent off to run.
▪ The metadata database, usually PostgreSQL or MySQL, stores every DAG run, every task state, and every retry. If the scheduler is the brain, this is the memory.
▪ The executor decides where tasks actually run. It might run them on the same machine, hand them to a pool of worker machines, or start a fresh container for each one.
▪ Workers are the machines or containers doing the real work of each task.
▪ The API server powers the web interface and the REST API. In Airflow 3, workers report back through this API instead of writing straight to the database, which improves security and isolation.
▪ The triggerer is a lightweight service that waits on many slow events at once, such as a file landing in storage, without tying up a worker for each wait.
The choice of executor shapes how Airflow behaves as it grows, so it's worth comparing the common options.
Executor options compared
Where teams put Airflow to work
The classic use is ETL pipelines. ETL stands for extract, transform, load: pull data out of a source like a payment system or CRM, clean and reshape it, and load it into a warehouse such as Snowflake, BigQuery, or Redshift. Airflow runs each of those stages as tasks, checks that each one finished, and only moves forward when it's safe.
That's only the starting point. Here are other jobs teams commonly hand to Airflow:
▪ Machine learning upkeep. A DAG pulls fresh data every week, retrains a model, compares its accuracy with the current version, and only deploys the new model if it does better.
▪ Reporting. Finance teams schedule month-end reports that depend on dozens of upstream tables being ready first.
▪ AI and LLM jobs. In April 2026, the project released a Common AI provider that adds operators for calling large language models and AI agents, with support for more than 20 model providers in one package. Each model call becomes a named task that is logged and can be retried on its own.
▪ Reverse ETL. Teams push cleaned warehouse data back into business tools, such as sending customer scores to a CRM so the sales team sees them.
For office teams and founders, the appeal is workflow automation that someone can actually audit. When a report is wrong, you can open the interface, find the exact run, see which task failed or which one ran late, and read its logs. A script on someone's laptop offers none of that.
How Airflow compares with other options
Airflow isn't the only orchestrator, and it isn't always the right pick. The table below compares it with plain cron (the scheduler built into Linux) and two popular open-source alternatives.
Airflow and its alternatives
If you have three scripts that rarely fail, cron is fine. Once jobs depend on each other, run across several systems, or matter to revenue, a proper orchestrator pays for itself. Among orchestrators, Airflow's biggest advantage is its ecosystem. Someone has almost certainly already written the connector you need. Its biggest cost is operational weight. Running it well at scale takes skill.
Airflow is also not a streaming tool. It thinks in runs: a batch of work that starts and ends. Reacting to each click within milliseconds is a job for streaming systems like Apache Kafka or Apache Flink, though Airflow can manage the jobs around them.
When things go wrong: the hard parts of orchestration
Real pipelines are messy. These are the problems that decide whether an Airflow setup earns trust or creates more work.
Data gaps
Go back to the opening story. The order export ran late, and the loading step processed an empty file. In Airflow, there are a few ways to stop that from happening.
The first is a sensor, a special task that waits until a condition is true, such as "the file exists and is bigger than zero bytes." Sensors can run in reschedule mode, where they check, release their worker slot, and check again later. Even better are deferrable operators, which hand the waiting over to the triggerer service. A single triggerer can watch thousands of these waits at once, which costs far less than keeping thousands of workers busy doing nothing.
The second defense is knowing which day a run is really about. In Airflow 2, a daily run labeled June 3 covered June 3's data and only started after midnight on June 4, once the day was over. That confused a lot of people. Airflow 3 changed the default for cron-style schedules, so a run labeled June 3 now starts at midnight on June 3. Teams moving from Airflow 2 need to check every query that uses the run date, or their pipelines will quietly process the wrong day.
The third is the backfill, which means re-running a pipeline for past dates that were missed or processed wrongly. Airflow 3 runs backfills inside the scheduler and lets you start them from the interface. Note that Airflow 3 also changed a default: catchup is now off unless you turn it on. In older versions, a new DAG with a start date six months in the past would immediately launch every missed daily run, sometimes hundreds at once.
Backfills only work safely if tasks are idempotent. That word means running a task twice gives the same result as running it once. A load step that adds rows each time it runs will create duplicates on a re-run. A load step that replaces the data for that specific date will not. This one design choice causes more trouble in ETL pipelines than almost anything else.
Conflicting signals
The trickiest failures are the ones where Airflow shows green and the data is still wrong. A task reports success because the SQL ran without errors, even though it returned half the expected rows. Airflow only knows what each task tells it.
The fix is to add checks as tasks of their own. The common SQL provider includes operators that test column values and row counts, and teams also plug in tools like Great Expectations or Soda. A typical rule: if today's row count is less than 70% of the seven-day average, fail the run and alert someone. Gartner estimated in 2021 that poor data quality costs organizations an average of USD 12.9 million a year, which gives a sense of why these checks are worth the extra minutes.
Conflicts also show up inside Airflow itself. A worker can crash or lose its network connection mid-task. The scheduler still thinks the task is running, but the task has stopped sending heartbeats (older documentation calls these "zombie" tasks). Airflow detects the missing heartbeat after a timeout and marks the task failed, which then triggers retries. During that timeout window, the interface shows a running task that isn't really running.
Trigger rules decide when a task runs based on what happened upstream. The default, all_success, waits for every upstream task to succeed. The one_failed rule suits alert tasks, and all_done runs regardless of outcome, which suits cleanup jobs. A common bug is a cleanup task left on the default rule. When anything upstream fails, the cleanup never runs, and temporary files pile up for weeks.
Real-time decisions
Since Airflow works in runs, its idea of "real time" is measured in minutes. Within that limit, it can make useful decisions as a pipeline runs.
Branching lets a task choose which path to follow next. For example, if a file contains international orders, send it to the currency conversion step; if not, skip ahead. Short-circuit tasks can stop a run early when there's nothing to process, marking later steps as skipped instead of failed.
Airflow 3 added event-driven scheduling. Instead of checking a clock, a DAG can start when an outside system reports that something changed, such as a message arriving on a queue. This cuts the lag between "the data is ready" and "the pipeline starts." Airflow 3.1 went further with human-in-the-loop steps, where a run pauses and waits for a person to approve, reject, or pick an option in the interface. That suits cases like approving a large refund batch or reviewing AI-generated text before it gets published.
Exceptions and edge cases
A few situations catch even experienced teams off guard:
▪ Daylight saving time. A job scheduled for 2:30 a.m. local time can be skipped on the night clocks jump forward, because 2:30 never happens. Scheduling in UTC avoids this.
▪ Retries with side effects. If a task sends emails and fails halfway, a retry may send the first half again. Design each task so a retry is safe, or split sending into smaller tasks.
▪ Passing too much data between tasks. Airflow lets tasks share small values through a feature called XCom, which stores them in the metadata database by default. Passing a large table this way bloats the database. Pass a file path instead, and keep the actual data in cloud storage.
▪ Tasks that hang. Without a timeout, a stuck API call can hold a worker slot for days. Setting an execution timeout on every task turns a silent hang into a visible failure.
▪ Changing code mid-run. Before Airflow 3, editing a DAG while it was running could make the history confusing, since the interface always showed the newest version. DAG versioning, the most requested feature in the community survey, now records which version of the code each run used.
▪ Dynamic fan-out. Dynamic task mapping lets one task split into many copies at run time, such as one copy per file found. By default, Airflow caps this at 1,024 copies per mapped task, so a day with 5,000 files will fail unless someone raises the limit.
How Airflow behaves under pressure and at scale
As a deployment grows, data pipeline orchestration turns into real engineering work. Several pressure points show up again and again.
The first is file parsing. Airflow re-reads each DAG file roughly every 30 seconds by default, and any code at the top level of the file, outside the tasks, runs on every read. A file that queries a database at the top level does so thousands of times a day. Across a few hundred files, parsing alone can max out the CPU.
The second is the metadata database. Every task state change is a write. At high volume, the database becomes the bottleneck. Teams typically put a connection pooler such as PgBouncer in front of PostgreSQL, and they regularly clean out old run records, since history tables can grow into millions of rows.
The third is concurrency. Airflow has several limits that stack on top of each other. Global parallelism caps tasks across the whole system, with a default of 32. Per-DAG limits cap how many tasks and runs one DAG can have at once. Pools cap how many tasks can hit a shared resource. The default pool has 128 slots, and teams create smaller pools to protect fragile systems. If a partner API allows only five calls at a time, a pool of five slots keeps Airflow from overwhelming it. When tasks sit queued for no clear reason, one of these limits is usually the cause.
The fourth is the midnight rush. When hundreds of DAGs are scheduled for "@daily," they all become due at the same moment. Queues fill up and short tasks wait behind long ones. Spreading start times across the night often helps more than adding hardware.
Since version 2.0, Airflow can run several schedulers at once, so if one crashes, the others keep going. They coordinate through locks in the database, one more reason it needs care as you grow.
Running Airflow: self-hosted or managed
You can install Apache Airflow on your own servers or on Kubernetes using the official Helm chart. Self-hosting gives full control and costs nothing in license fees, but your team owns upgrades, security patches, database care, and scaling.
The alternative is a managed service. The three best-known options are Amazon's managed Airflow service (MWAA), Google Cloud Composer, and Astronomer's Astro. Each runs the scheduler, database, and workers for you. Astronomer, for example, says it supports Airflow 2 on its platform through April 2027, a year past the open-source end of life. The trade-off is control. Managed services can lag behind the newest release, and they bill every month whether your DAGs run or not.
A reasonable rule: if your team has fewer than two people who are comfortable running Kubernetes and PostgreSQL in production, start managed. Many teams that build ETL pipelines for a living have learned that keeping an orchestrator healthy is a real part-time job.
Getting started without getting burned
If you're a founder, developer, or operations lead thinking about Airflow, this order of steps tends to work well:
1. List your scheduled jobs and sketch how they depend on each other. If nothing depends on anything else, you may not need Airflow yet.
2. Run Airflow locally with the official Docker Compose file or the Astro CLI, and rebuild one real pipeline end to end.
3. Make every task idempotent from day one. Write each load so a re-run replaces data instead of adding to it.
4. Add retries, an execution timeout, and a failure alert to every task as defaults.
5. Add at least one data quality check after each load step.
6. Keep DAG files light. Put heavy logic in separate Python modules or external tools.
7. Store passwords and API keys in Airflow connections or a secrets manager, never in DAG code.
8. Start on Airflow 3. There's no good reason to begin a new project on a version that no longer gets security fixes.
Small teams can get real value from workflow automation without a big platform build. One solid DAG that replaces five fragile scripts is a good first win.
Conclusion
The empty-file problem from the opening does its worst damage to trust. People stop believing the dashboard, start exporting spreadsheets by hand, and the data team spends Mondays explaining what went wrong. Apache Airflow doesn't fix bad data by itself. What it gives you is a single place where every step, every dependency, every retry, and every failure is written down and visible.
Good data pipeline orchestration comes down to a few habits: wait for data before using it, check data after loading it, make re-runs safe, and spread the load. Airflow gives you the tools for all four. Whether it fits depends on how many jobs you run, how tightly they depend on each other, and whether you want to run the platform yourself.